<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://igorgukasyan.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://igorgukasyan.github.io/" rel="alternate" type="text/html" /><updated>2025-04-03T08:30:27+00:00</updated><id>https://igorgukasyan.github.io/feed.xml</id><title type="html">Igor Gukasyan</title><subtitle>Igor Gukasyan&apos;s awesome data science portfolio!
</subtitle><author><name>Igor Gukasyan</name><email>igorgukasyan00@gmail.com</email></author><entry><title type="html">Creating a no-fluff Telegram-based newsletter that you can customize</title><link href="https://igorgukasyan.github.io/2025/04/02/daily_digest.html" rel="alternate" type="text/html" title="Creating a no-fluff Telegram-based newsletter that you can customize" /><published>2025-04-02T00:00:00+00:00</published><updated>2025-04-02T00:00:00+00:00</updated><id>https://igorgukasyan.github.io/2025/04/02/daily_digest</id><content type="html" xml:base="https://igorgukasyan.github.io/2025/04/02/daily_digest.html"><![CDATA[<h3 id="the-why">The Why</h3>

<p>Telegram turned my media consumption habits and preferences upside down with the rollout and popularization of ‘channels’. Channels are essentially just curated message boards, where only one party can post on the main board, while others might be able to comment/interact with it in a different way. Channels reporting news are extremely popular on Telegram, getting millions of subscribers. Consuming news through snippets that someone carefully tailored to your political bubble’s status quo is just much more fun than reading long articles. Also it drives engagement growth.</p>

<p>Despite now reading news snippets, you still find yourself spending just as much time as you would were you to read the original article. That is because news happens all the time, and with a shorter pipeline from ‘spawned’ to ‘reported’, more and more things are now being posted that are not so newsworthy. All the news channels I am subscribed to produce more than 300 snippets per day combined, which is almost as much as Kanye posts on Twitter. Some of the problems it creates:</p>

<ul>
  <li>You don’t have time to critically assess what you read</li>
  <li>You clutter your mind with <del>bullshit</del> unimportant things</li>
  <li>You waste time</li>
  <li>…</li>
</ul>

<h3 id="conceptual-model">Conceptual Model</h3>

<p>Heavily inspired by <a href="https://www.newsminimalist.com/">newsminimalist</a> and my own laziness, I created a Telegram bot that takes news posts from channels you select, analyzes their importance and spits out only the highest-performing ones. A rough conceptual model:</p>

<p><img src="/assets/images/dd_conceptual_model.png" alt="" class="small-image" /></p>

<p>In words: through Telegram’s frontend, the user selects the channels they want to subscribe to. These channels are stored in a single table in a local SQLite database. Every morning, a Cron job activates, pulling all the posts you missed the previous day. Those posts are cleaned and turned into arrays of numbers, which are then classified as either worthy or unworthy of your attention. Finally, the posts are sent back to the user.</p>

<p>The project turned out to be a bit larger than I expected, so I am dedicating two posts to it. In this one, I will talk about data collection, preprocessing and the machine learning behind it.</p>

<h3 id="the-data">The Data</h3>

<p>I needed a lot of training data, so I chose six news channels that had consistently delivered news in a formal or semi-formal format. The channels are ‘Раньше всех. Ну почти.’, ‘РИА Новости’, ‘Varlamov News’, ‘Медуза — LIVE’, ‘BRIEFLY’, and ‘Ньюсач/Двач’. From each channel, I extracted 10,000 most recent posts with the following functions:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">from</span> <span class="nn">telethon</span> <span class="kn">import</span> <span class="n">TelegramClient</span>
<span class="kn">import</span> <span class="nn">asyncio</span>

<span class="k">async</span> <span class="k">def</span> <span class="nf">fetch_messages</span><span class="p">(</span><span class="n">channel</span><span class="p">,</span> <span class="n">limit</span><span class="p">):</span>
    <span class="s">""" Fetch messages from single channel."""</span>
    <span class="k">try</span><span class="p">:</span>
        <span class="n">message_list</span> <span class="o">=</span> <span class="p">[]</span>
        <span class="k">async</span> <span class="k">for</span> <span class="n">message</span> <span class="ow">in</span> <span class="n">client</span><span class="p">.</span><span class="n">iter_messages</span><span class="p">(</span><span class="n">channel</span><span class="p">,</span> <span class="n">limit</span><span class="p">):</span>
            <span class="n">message_list</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">message</span><span class="p">.</span><span class="n">text</span><span class="p">)</span>
        <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'Finished fetching messages from </span><span class="si">{</span><span class="n">channel</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">channel</span><span class="p">,</span> <span class="n">message_list</span>
    <span class="k">except</span> <span class="nb">Exception</span> <span class="k">as</span> <span class="n">e</span><span class="p">:</span>
        <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'Error fetching messages from </span><span class="si">{</span><span class="n">channel</span><span class="si">}</span><span class="s">: </span><span class="si">{</span><span class="n">e</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">channel</span><span class="p">,</span> <span class="p">[]</span>

<span class="k">async</span> <span class="k">def</span> <span class="nf">main</span><span class="p">():</span>
    <span class="s">"""Fetching messages from all channels."""</span>
    <span class="k">try</span><span class="p">:</span> 
        <span class="n">post_history</span> <span class="o">=</span> <span class="p">{}</span>
        <span class="k">for</span> <span class="n">channel</span> <span class="ow">in</span> <span class="n">channels</span><span class="p">:</span> 
            <span class="n">dialogs</span> <span class="o">=</span> <span class="k">await</span> <span class="n">client</span><span class="p">.</span><span class="n">get_dialogs</span><span class="p">()</span>
            <span class="n">channel</span><span class="p">,</span> <span class="n">messages</span> <span class="o">=</span> <span class="k">await</span> <span class="n">fetch_messages</span><span class="p">(</span><span class="n">channel</span><span class="p">,</span> <span class="n">limit</span><span class="p">)</span>
            <span class="k">if</span> <span class="n">messages</span><span class="p">:</span> 
                <span class="n">post_history</span><span class="p">[</span><span class="n">channel</span><span class="p">]</span> <span class="o">=</span> <span class="n">messages</span>
        <span class="k">with</span> <span class="nb">open</span><span class="p">(</span><span class="s">'./data/post_history.json'</span><span class="p">,</span> <span class="s">'w'</span><span class="p">)</span> <span class="k">as</span> <span class="n">f</span><span class="p">:</span>
            <span class="n">json</span><span class="p">.</span><span class="n">dump</span><span class="p">(</span><span class="n">post_history</span><span class="p">,</span> <span class="n">f</span><span class="p">,</span> <span class="n">ensure_ascii</span><span class="o">=</span><span class="bp">False</span><span class="p">)</span>
    <span class="k">except</span> <span class="nb">Exception</span> <span class="k">as</span> <span class="n">e</span><span class="p">:</span> 
        <span class="k">print</span><span class="p">(</span><span class="sa">f</span><span class="s">'Error: </span><span class="si">{</span><span class="n">e</span><span class="si">}</span><span class="s">'</span><span class="p">)</span>


</code></pre></div></div>

<p>Afterwards I cleaned them, removing links, deleting markdown symbols,etc., and was left with around 50,000 posts.</p>

<h4 id="scoring-50000-news-articles-on-importance">Scoring 50,000 News Articles on Importance</h4>

<p>I left data labeling to LLMs, once again drawing heavy inspiration from <a href="https://www.newsminimalist.com/">newsminimalist</a>. I used the following prompt to generate multiple scores for each snippet:</p>

<blockquote>
  <h5 id="instruction">Instruction:</h5>
  <p>Analyze the following Russian news snippet and provide scores for each of the following dimensions. Please respond in the format: “Dimension: Score” (e.g., “Scale: 8”). Ensure your response is concise and only includes the dimension name followed by a score.</p>
  <h5 id="dimensions">Dimensions:</h5>
  <ol>
    <li><strong>Scale</strong>: How broadly the event affects humanity.</li>
    <li><strong>Impact</strong>: How strong the immediate effect is.</li>
    <li><strong>Novelty</strong>: How unique and unexpected is the event.</li>
    <li><strong>Potential</strong>: How likely it is to shape the future.</li>
    <li><strong>Legacy</strong>: How likely it is to be considered a turning point in history or a major milestone.</li>
    <li><strong>Positivity</strong>: How positive is the event.
      <h5 id="input">Input:</h5>
      <p>[Insert Russian news snippet here]</p>
      <h5 id="response-format">Response Format:</h5>
      <p>Scale: [Score]<br />
Impact: [Score]<br />
Novelty: [Score]<br />
Potential: [Score]<br />
Legacy: [Score]<br />
Positivity: [Score]</p>
    </li>
  </ol>
</blockquote>

<p>Final score weighs the factors and is calculated with the following weights and function:</p>

<div class="language-python highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">coefs</span> <span class="o">=</span> <span class="p">{</span>
    <span class="s">"Scale"</span><span class="p">:</span> <span class="mf">0.25</span><span class="p">,</span>
    <span class="s">"Impact"</span><span class="p">:</span> <span class="mf">0.25</span><span class="p">,</span>
    <span class="s">"Novelty"</span><span class="p">:</span> <span class="mf">0.05</span><span class="p">,</span>
    <span class="s">"Potential"</span><span class="p">:</span> <span class="mf">0.25</span><span class="p">,</span>
    <span class="s">"Legacy"</span><span class="p">:</span> <span class="mf">0.15</span><span class="p">,</span>
    <span class="s">"Positivity"</span><span class="p">:</span> <span class="mf">0.05</span>
<span class="p">}</span>

<span class="k">def</span> <span class="nf">calculate_scores</span><span class="p">(</span><span class="n">responses</span><span class="p">):</span>
    <span class="n">final_scores</span> <span class="o">=</span> <span class="p">[]</span>
    <span class="k">for</span> <span class="n">score</span> <span class="ow">in</span> <span class="n">responses</span><span class="p">:</span> 
        <span class="n">all_scores</span> <span class="o">=</span> <span class="n">re</span><span class="p">.</span><span class="n">findall</span><span class="p">(</span><span class="sa">r</span><span class="s">'\d'</span><span class="p">,</span> <span class="n">score</span><span class="p">)</span>
        <span class="n">all_scores</span><span class="o">=</span> <span class="p">[</span><span class="nb">int</span><span class="p">(</span><span class="n">s</span><span class="p">)</span> <span class="k">for</span> <span class="n">s</span> <span class="ow">in</span> <span class="n">all_scores</span><span class="p">]</span>
        <span class="n">final_score</span> <span class="o">=</span> <span class="nb">round</span><span class="p">(</span><span class="nb">sum</span><span class="p">([</span><span class="n">coef</span> <span class="o">*</span> <span class="n">all_scores</span><span class="p">[</span><span class="n">i</span><span class="p">]</span> <span class="k">for</span> <span class="n">i</span><span class="p">,</span> <span class="n">coef</span> <span class="ow">in</span> <span class="nb">enumerate</span><span class="p">(</span><span class="n">coefs</span><span class="p">.</span><span class="n">values</span><span class="p">())]),</span><span class="mi">1</span><span class="p">)</span>
        <span class="n">final_scores</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">final_score</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">final_scores</span>

</code></pre></div></div>
<p>These weights reflect what I personally expect from my newsletter, so you might find them somewhat arbitrary. That is, however, not the main problem with my approach. To radically decrease investments into this inherently net-negative project, I opted for a smaller, cheaper LLM: ChatGPT-4o mini. This later comes back to bit me in the ass, as I will mention. That said, I did conduct multiple sanity checks to ensure the scores made any sense - and they did! Here are a couple of examples (translated from Russian to English):</p>

<table>
  <thead>
    <tr>
      <th>TG Post</th>
      <th>Importance by 4o-mini</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Reuters: Trump says he will discuss power plants, territories with Putin in talks to end military conflict in Ukraine</td>
      <td>8.3</td>
    </tr>
    <tr>
      <td>VPN without traffic and device restrictions from 152₽ per month</td>
      <td>3.7</td>
    </tr>
    <tr>
      <td>Slovakia will not participate in any military missions in Ukraine and will not provide “a single cent” in military aid to Kyiv, Prime Minister Fico said.</td>
      <td>5.2</td>
    </tr>
    <tr>
      <td>Escort girl entered the Betting League chat and left with a jackpot</td>
      <td>3.7</td>
    </tr>
  </tbody>
</table>

<p>ChatGPT-4o successfully ranked both commercials low, while boosting the score of the important snippet. Seeing these scores, one might think we are close to AGI, since even a low-cost model understands that Slovakia’s politics is unimportant. Despite many good hits, the model, just like an average Internet user, lacked critical thinking and ranked especially arrogant commercials, lies, and random things highly:</p>

<table>
  <thead>
    <tr>
      <th>TG Post</th>
      <th>Importance by 4o-mini</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>ChatGPT and Midjourney to be added to Telegram!</td>
      <td>6.2</td>
    </tr>
    <tr>
      <td>Prada and Axiom Space unveil spacesuit for first moon landing in 50 years</td>
      <td>8.2</td>
    </tr>
    <tr>
      <td>Trump: ‘We can end the war in Ukraine within weeks’</td>
      <td>8.1</td>
    </tr>
  </tbody>
</table>

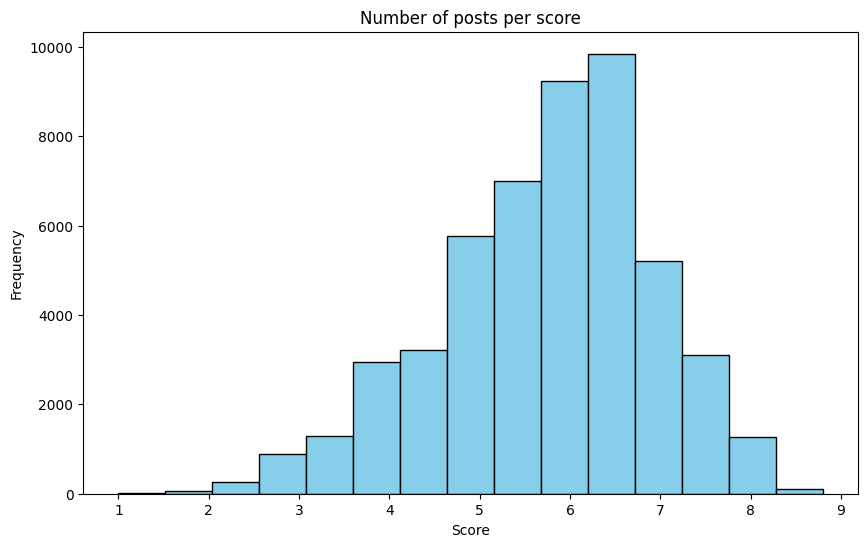
<p>Below you can find the distribution of the scores. Something like a normal distribution with a mean of around 6.5 can be observed. I believe the average is higher than what <a href="https://www.newsminimalist.com/">newsminimalist</a> reports because a cheaper model is much more impressionable and, as I already mentioned, can fall for simple tricks.</p>

<p><img src="/assets/images/dd_post_score_hist.png" alt="" class="small-image" /></p>

<p>Bad scoring practices create the <em>shit in, shit out</em> problem: if the scores lack intrinsic insight, no model will be able to work with them effectively. This does not have much impact on my project much since I am just happy to be here [and showcase my skills].</p>

<h3 id="quick-dive-into-the-data">Quick Dive Into the Data</h3>

<p>Below is a wordcloud I created from the entirety of the data that I gathered. I lemmatized the text before to get a more general view of the corpus. For the English speakers: most popular words were “year”, “say”, “also”, “Russia”, “Trump”, which makes sense.</p>

<blockquote>
  <p>To lemmatize means to find the ‘lemma’ or root form of a word.</p>
</blockquote>

<p><img src="/assets/images/dd_wordcloud.png" alt="" class="small-image" /></p>

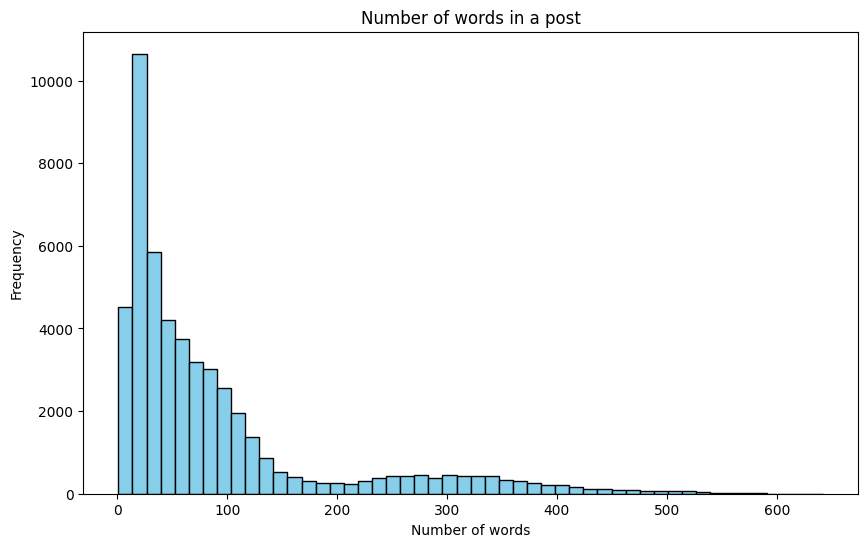
<p>Now let’s take a look into the sizes of posts. The distribution is heavily skewed to the right, with most posts having around 20 words in them. A small bump at around 300 is caused by the channel ‘BRIEFLY’, since they group snippets together and post larger messages. There is a moderate correlation between post size and post score, with a Pearson correlation coefficient of 0.37. I believe it is caused by posts from ‘BRIEFLY’ getting ranked highly since they contain more information in a single post.</p>

<p><img src="/assets/images/dd_post_size_hist.png" alt="" class="small-image" /></p>

<blockquote class="orange">
  Pearson correlation is a measure of a linear relationship between two continuous variables.
</blockquote>

<h3 id="translating-human-language-into-numbers">Translating Human Language Into Numbers</h3>

<p>Collecting scores only gives us the response variable, and we still need to use something as a predictor. We cannot, unfortunately, use documents as they are for model training - we need to translate them from human language into a format that machines understand, i.e., numbers. I applied two methods of calculating document embeddings: training own Doc2Vec model and using a pre-trained BERT model. I trained my own Doc2Vec model and used the pre-trained BERT model rubert-tiny-turbo to generate embeddings. I chose it because of its outstanding size/performance ratio. Benchmark results can be found <a href="https://huggingface.co/sergeyzh/rubert-tiny-turbo">here</a>.</p>

<blockquote class="red">
  Doc2Vec is an extension of Word2Vec, which embeds words in a vector space using a shallow neural network. Doc2Vec we act as if all documents have another word-like vector which contributes to all training predictions and it a doc-vector.
</blockquote>

<blockquote class="green">
  BERT is a language model that understands text by considering the context of each word in both directions. It uses the transformer architecture, which applies attention mechanisms to capture relationships between words regardless of their position in a sentence.
</blockquote>

<h3 id="training-a-model-to-predict-importance">Training a Model to Predict Importance</h3>

<p>Essentially, the problem I need to tackle is classifying news snippets as important or unimportant. Therefore, to keep things simple, I decided to choose a threshold value of <strong>6</strong> and fit a logistic regression model to the data. Doc2Vec requires two important hyperparameters: vector size and epochs (i.e., how many times the model goes through the corpus). To find the optimal values, I fitted a logistic regression for multiple combinations, with the best one achieving a balanced accuracy of 71% and an F1 score of 0.65. Embeddings generated by a pre-trained BERT model showed much better performance, with accuracy of almost 80% and F1 score of 0.75. F1 score is calculated as follows:</p>

\[F_1 = \frac{2 \cdot (\text{Precision} \cdot \text{Recall})}{\text{Precision} + \text{Recall}}\]

\[\text{Precision} = \frac{TP}{TP + FP}, \quad \text{Recall} = \frac{TP}{TP + FN}\]

<p><strong>Doc2Vec (test data):</strong></p>

<table>
  <thead>
    <tr>
      <th>Vector Size</th>
      <th>Epochs</th>
      <th>Balanced Accuracy</th>
      <th>F1 Score</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>10</td>
      <td>40</td>
      <td>0.692</td>
      <td>0.630</td>
    </tr>
    <tr>
      <td>10</td>
      <td>60</td>
      <td>0.699</td>
      <td>0.639</td>
    </tr>
    <tr>
      <td>30</td>
      <td>40</td>
      <td>0.684</td>
      <td>0.627</td>
    </tr>
    <tr>
      <td><strong>30</strong></td>
      <td><strong>60</strong></td>
      <td><strong>0.705</strong></td>
      <td><strong>0.645</strong></td>
    </tr>
    <tr>
      <td>50</td>
      <td>40</td>
      <td>0.682</td>
      <td>0.623</td>
    </tr>
    <tr>
      <td>50</td>
      <td>60</td>
      <td>0.687</td>
      <td>0.633</td>
    </tr>
    <tr>
      <td>100</td>
      <td>40</td>
      <td>0.684</td>
      <td>0.629</td>
    </tr>
    <tr>
      <td>100</td>
      <td>60</td>
      <td>0.689</td>
      <td>0.632</td>
    </tr>
    <tr>
      <td>150</td>
      <td>40</td>
      <td>0.681</td>
      <td>0.620</td>
    </tr>
    <tr>
      <td>150</td>
      <td>60</td>
      <td>0.692</td>
      <td>0.630</td>
    </tr>
  </tbody>
</table>

<p><strong>rubert-tiny-turbo:</strong></p>

<table>
  <thead>
    <tr>
      <th>Dataset</th>
      <th>Balanced Accuracy</th>
      <th>Accuracy</th>
      <th>F1 Score</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Train</td>
      <td>0.788</td>
      <td>0.788</td>
      <td>0.748</td>
    </tr>
    <tr>
      <td>Test</td>
      <td>0.790</td>
      <td>0.790</td>
      <td>0.750</td>
    </tr>
  </tbody>
</table>

<h3 id="creating-the-bot">Creating the Bot</h3>

<p>The Telegram bot that we need to make is rather simple, we just need to account for various situations (e.g., a user wants to resubscribe to a channel, no news marked as important, etc.) Full code can be found <a href="https://github.com/igorgukasyan/daily_digest">here</a>.</p>

<h3 id="closing-thoughts">Closing Thoughts</h3>

<p>In the future, I would like to re-do this project with proper data labeling and model training. I believe that a ‘great content filter’ would be valuable and could be implemented in various ways across different platforms. If you feel like participating, either through labor, funding or in any other way, feel free to reach out.</p>]]></content><author><name>Igor Gukasyan</name><email>igorgukasyan00@gmail.com</email></author><summary type="html"><![CDATA[The Why]]></summary></entry><entry><title type="html">Breaking Down My Master Thesis</title><link href="https://igorgukasyan.github.io/2025/03/11/breaking-down-my-master-thesis.html" rel="alternate" type="text/html" title="Breaking Down My Master Thesis" /><published>2025-03-11T00:00:00+00:00</published><updated>2025-03-11T00:00:00+00:00</updated><id>https://igorgukasyan.github.io/2025/03/11/breaking-down-my-master-thesis</id><content type="html" xml:base="https://igorgukasyan.github.io/2025/03/11/breaking-down-my-master-thesis.html"><![CDATA[<h4 id="motivation-behind-the-topic">Motivation Behind the Topic</h4>
<p>A little over a decade ago, a new genre emerged from the depths of the Russian rap scene. As of now, it has no name (to my knowledge) and can take many forms, though it usually appears as rap. The genre’s distinctive feature is highly conceptual, linguistically experimental, neologism-heavy lyrics. Examples of artists include <a href="https://genius.com/artists/Ezhemesyachnye">Ezhemesyachnye</a>, <a href="https://genius.com/artists/Husky">Husky</a>, <a href="https://genius.com/artists/Makulatura">makulatura</a>, <a href="https://genius.com/artists/Krovostok">Krovostok</a> and <a href="https://genius.com/artists/Pasha-technique">Pasha Technique</a>. I think a name like <strong>“solyanka”</strong> can stick. Solyanka is a common dish, or rather, a culinary disaster of one, in post-Soviet countries, whose name became a phraseological unit meaning ‘a mix of everything’. In this context, solyanka is used as a metaphor for content-rich. One could argue solyanka the dish is as abstract in its contents as the music of the aforementioned bands.</p>

<p>Apple Music was not able to reliably distinguish between rap and solyanka, often creating poorly assembled playlists for me. Classifying solyanka versus not solyanka is a rather thrilling challenge, but too narrow for a master’s thesis. Instead, I decided to explore whether modeling lyrics — the defining feature of solyanka — could improve the performance of content-based music recommendation systems in general.</p>

<h4 id="why-it-matters">Why It Matters</h4>
<p>Predicting which songs a user might like based on the listening histories of similar users generally yields a better result than using only content-based methods (audio, metadata, etc.). However, when songs have few or no streams — which is common for solyanka —  content-based methods are the only viable option for recommendations. This makes it essential to find effective ways to represent song content in a computer-friendly manner.</p>

<p>To achieve this, I created multiple variables to model the complexity of song lyrics. Four of these variables significantly improved recommendation quality, including two which could be directly linked to solyanka: <strong>MTLD</strong> and <strong>lexical sophistication</strong>.</p>

<ul>
  <li><strong>MTLD (Measure of Textual Lexical Diversity)</strong> is calculated relatively simply and measures the proportion of unique words in a song. It is widely used in linguistic assessments and has applications in monitoring language impairments. Interestingly, MTLD also proved useful in predicting songs a person might enjoy.</li>
  <li><strong>Lexical sophistication</strong> is the percentage of words not found in the 5,000 most commonly used words. I used the same method that Grammarly employs to calculate its sophistication index.</li>
</ul>

<p>You can find the list of all variables in my <a href="/_posts/2025-03-11-breaking-down-my-master-thesis.md">paper</a>.</p>

<h4 id="why-its-difficult-or-nearly-impossible">Why It’s Difficult (or Nearly Impossible)</h4>
<p>Solyanka, however, is not characterized just by lyrical complexity. It is a genre deeply rooted in the Russian culture and mindset, both of which are arguably impossible to model. In music recommendation literature, this phenomenon is called the <strong>Semantic Gap</strong>.</p>
<blockquote>
  <p>“The semantic gap is the discrepancy between what can be extracted from music (i.e., semantic or audio features), and high-level human perception of these features”.</p>
</blockquote>

<p>One way to bridge the semantic gap is by modeling as many features as possible. In an ideal scenario, a data-omniscient supercomputer could fully capture the intricacies of solyanka, eliminating the gap altogether.</p>

<h4 id="feature-importance-and-weighting-not-included-in-the-paper">Feature Importance and Weighting (Not Included in the Paper)</h4>
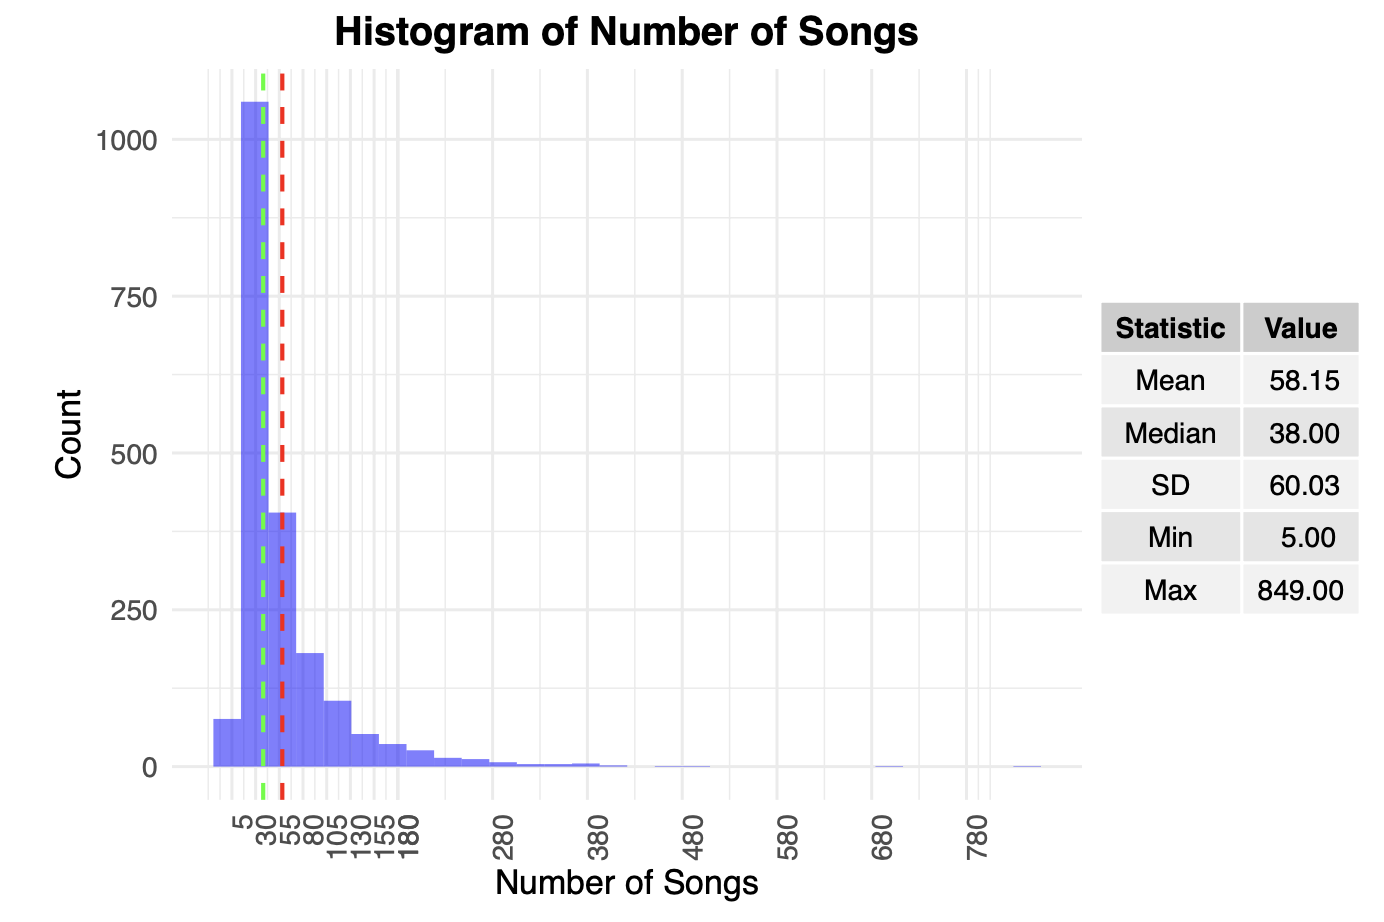
<p>One major idea I had was to account for the varying importance of features for different users. While this is not groundbreaking, it becomes a challenging task when a user has only a few streamed songs. In my dataset, most users had under 38 unique streamed songs. With over 70 features and only 38 observations, calculating feature importance became a major challenge due to the <em>curse of dimensionality</em> and the risk of <em>overfitting</em>.</p>

<p><img src="/assets/images/num_songs_histogram_master_thesis.png" alt="" class="small-image" /></p>

<p>For song similarity calculations, I used <em>weighted cosine similarity</em> as implemented in <a href="https://github.com/scipy/scipy/blob/v1.4.1/scipy/spatial/distance.py#L724-L766">scipy</a>:</p>

\[\theta = \dfrac{\sum_{i} w_i u_i v_i}{\sqrt{\sum_i}w_i u_i^2 \cdot \sqrt{\sum_i}w_i v_i^2}\]

<p>To determine weights for individual variables, I used a transformed version of their feature importances/coefficients, calculated through a classification task: predicting whether a user listened to a song more than the average number of times.</p>

<p>Finding the optimal weights for each variable posed another challenge. A naive approach like <strong>random search</strong> was infeasible: with just 10 variables and 10 possible values each, the search space ballooned to 10 billion combinations. Instead, I needed a more efficient approach based on available user data.</p>

<p>Below are the R implementations for <strong>linear SVM</strong> and <strong>XGBoost</strong> used to calculate user-specific feature weights:</p>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">calculate_user_weights</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="k">function</span><span class="p">(</span><span class="n">user_song_profiles</span><span class="p">,</span><span class="w"> </span><span class="n">user_utility_vector</span><span class="p">)</span><span class="w"> </span><span class="p">{</span><span class="w">
  </span><span class="n">set.seed</span><span class="p">(</span><span class="m">7</span><span class="p">)</span><span class="w">
  </span><span class="n">data</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">data.frame</span><span class="p">(</span><span class="n">cbind</span><span class="p">(</span><span class="n">user_song_profiles</span><span class="p">,</span><span class="w"> </span><span class="n">user_utility_vector</span><span class="p">))</span><span class="w">
  </span><span class="n">colnames</span><span class="p">(</span><span class="n">data</span><span class="p">)[</span><span class="n">ncol</span><span class="p">(</span><span class="n">data</span><span class="p">)]</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="s2">"utility"</span><span class="w">
  </span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">ifelse</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="w"> </span><span class="o">&gt;=</span><span class="w"> </span><span class="n">mean</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="p">),</span><span class="w"> </span><span class="m">1</span><span class="p">,</span><span class="w"> </span><span class="m">0</span><span class="p">)</span><span class="w">
  </span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">as.factor</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="p">)</span><span class="w">
  
  </span><span class="n">classifier</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">svm</span><span class="p">(</span><span class="n">formula</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">utility</span><span class="w"> </span><span class="o">~</span><span class="w"> </span><span class="n">.</span><span class="p">,</span><span class="w"> 
                   </span><span class="n">data</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">data</span><span class="p">,</span><span class="w"> 
                   </span><span class="n">type</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s1">'C-classification'</span><span class="p">,</span><span class="w"> 
                   </span><span class="n">kernel</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s1">'linear'</span><span class="p">,</span><span class="w">
                   </span><span class="n">class.weights</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s2">"inverse"</span><span class="p">)</span><span class="w">
  
  </span><span class="n">weights_vector</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">t</span><span class="p">(</span><span class="n">t</span><span class="p">(</span><span class="n">classifier</span><span class="o">$</span><span class="n">coefs</span><span class="p">)</span><span class="w"> </span><span class="o">%*%</span><span class="w"> </span><span class="n">classifier</span><span class="o">$</span><span class="n">SV</span><span class="p">)</span><span class="w">
  
  </span><span class="n">set.seed</span><span class="p">(</span><span class="kc">NULL</span><span class="p">)</span><span class="w">
  </span><span class="nf">return</span><span class="p">(</span><span class="n">normalize</span><span class="p">(</span><span class="n">weights_vector</span><span class="p">))</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<div class="language-r highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">calculate_user_weights</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="k">function</span><span class="p">(</span><span class="n">user_song_profiles</span><span class="p">,</span><span class="w"> </span><span class="n">user_utility_vector</span><span class="p">)</span><span class="w"> </span><span class="p">{</span><span class="w">
   </span><span class="n">set.seed</span><span class="p">(</span><span class="m">7</span><span class="p">)</span><span class="w">
   </span><span class="n">data</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">data.frame</span><span class="p">(</span><span class="n">cbind</span><span class="p">(</span><span class="n">user_song_profiles</span><span class="p">,</span><span class="w"> </span><span class="n">user_utility_vector</span><span class="p">))</span><span class="w">
   </span><span class="n">colnames</span><span class="p">(</span><span class="n">data</span><span class="p">)[</span><span class="n">ncol</span><span class="p">(</span><span class="n">data</span><span class="p">)]</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="s2">"utility"</span><span class="w">
   </span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">ifelse</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="w"> </span><span class="o">&gt;=</span><span class="w"> </span><span class="n">mean</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="p">),</span><span class="w"> </span><span class="m">1</span><span class="p">,</span><span class="w"> </span><span class="m">0</span><span class="p">)</span><span class="w">
   </span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">as.factor</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="p">)</span><span class="w">
   </span><span class="n">class_freq</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">table</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="p">)</span><span class="w">
   </span><span class="n">num_samples</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">nrow</span><span class="p">(</span><span class="n">data</span><span class="p">)</span><span class="w">
   </span><span class="n">num_classes</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="nf">length</span><span class="p">(</span><span class="n">unique</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="p">))</span><span class="w">

   </span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">num_samples</span><span class="w"> </span><span class="o">/</span><span class="w"> </span><span class="p">(</span><span class="n">class_freq</span><span class="p">[</span><span class="nf">as.character</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">utility</span><span class="p">)]</span><span class="w"> </span><span class="o">*</span><span class="w"> </span><span class="n">num_classes</span><span class="p">)</span><span class="w">
   </span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">ifelse</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="w"> </span><span class="o">==</span><span class="w"> </span><span class="nf">max</span><span class="p">(</span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="p">),</span><span class="w"> </span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="o">*</span><span class="m">10</span><span class="p">,</span><span class="w"> </span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="p">)</span><span class="w">

   </span><span class="n">weights</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="w">

   </span><span class="n">xgb</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">caret</span><span class="o">::</span><span class="n">train</span><span class="p">(</span><span class="w">
     </span><span class="n">utility</span><span class="w"> </span><span class="o">~</span><span class="w"> </span><span class="n">.</span><span class="p">,</span><span class="w">
     </span><span class="n">data</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">data</span><span class="p">[,</span><span class="w"> </span><span class="o">-</span><span class="n">ncol</span><span class="p">(</span><span class="n">data</span><span class="p">)],</span><span class="w">
     </span><span class="n">method</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s2">"xgbTree"</span><span class="p">,</span><span class="w">
     </span><span class="n">weights</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">data</span><span class="o">$</span><span class="n">weight</span><span class="p">,</span><span class="w">
     </span><span class="n">trControl</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">trainControl</span><span class="p">(</span><span class="n">method</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s2">"cv"</span><span class="p">,</span><span class="w"> </span><span class="n">number</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">5</span><span class="p">),</span><span class="w">  </span><span class="n">Using</span><span class="w"> </span><span class="m">5</span><span class="o">-</span><span class="n">fold</span><span class="w"> </span><span class="n">cross</span><span class="o">-</span><span class="n">validation</span><span class="w">
     </span><span class="n">tuneGrid</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">expand.grid</span><span class="p">(</span><span class="w">
       </span><span class="n">nrounds</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">1000</span><span class="p">,</span><span class="w">
       </span><span class="n">max_depth</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">1</span><span class="p">,</span><span class="w">
       </span><span class="n">eta</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">0.025</span><span class="p">,</span><span class="w">
       </span><span class="n">gamma</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">0</span><span class="p">,</span><span class="w">
       </span><span class="n">colsample_bytree</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">0.2</span><span class="p">,</span><span class="w">
       </span><span class="n">min_child_weight</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">0</span><span class="p">,</span><span class="w">
       </span><span class="n">subsample</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="m">0.7</span><span class="w">
     </span><span class="p">)</span><span class="w">
   </span><span class="p">)</span><span class="w">

   </span><span class="n">predictor</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">Predictor</span><span class="o">$</span><span class="n">new</span><span class="p">(</span><span class="w">
     </span><span class="n">xgb</span><span class="p">,</span><span class="w">
     </span><span class="n">data</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="n">data</span><span class="p">[,</span><span class="w"> </span><span class="o">-</span><span class="n">ncol</span><span class="p">(</span><span class="n">data</span><span class="p">)],</span><span class="w">
     </span><span class="n">predict.fun</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="k">function</span><span class="p">(</span><span class="n">object</span><span class="p">,</span><span class="w"> </span><span class="n">newdata</span><span class="p">)</span><span class="w"> </span><span class="p">{</span><span class="w">
       </span><span class="n">predict</span><span class="p">(</span><span class="n">object</span><span class="p">,</span><span class="w"> </span><span class="n">newdata</span><span class="p">)</span><span class="w">
     </span><span class="p">}</span><span class="w">
   </span><span class="p">)</span><span class="w">

   </span><span class="n">imp</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">FeatureImp</span><span class="o">$</span><span class="n">new</span><span class="p">(</span><span class="n">predictor</span><span class="p">,</span><span class="w"> </span><span class="n">loss</span><span class="w"> </span><span class="o">=</span><span class="w"> </span><span class="s2">"ce"</span><span class="p">)</span><span class="w">

   </span><span class="n">weights_vector</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">as.matrix</span><span class="p">(</span><span class="n">imp</span><span class="o">$</span><span class="n">results</span><span class="o">$</span><span class="n">importance</span><span class="p">)</span><span class="w">
   </span><span class="n">rownames</span><span class="p">(</span><span class="n">weights_vector</span><span class="p">)</span><span class="w"> </span><span class="o">&lt;-</span><span class="w"> </span><span class="n">imp</span><span class="o">$</span><span class="n">results</span><span class="o">$</span><span class="n">feature</span><span class="w">

   </span><span class="nf">return</span><span class="p">(</span><span class="n">weights_vector</span><span class="p">)</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<h4 id="results">Results</h4>
<p>Using SVM, the model showed significant overfitting, as shown in the MAP@500 scores:</p>

<table>
  <thead>
    <tr>
      <th>Dataset</th>
      <th>MAP@500</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Weighted Test</td>
      <td>0.00251007</td>
    </tr>
    <tr>
      <td>Unweighted Test</td>
      <td>0.00236711</td>
    </tr>
    <tr>
      <td>Weighted Train</td>
      <td>0.04017487</td>
    </tr>
    <tr>
      <td>Unweighted Train</td>
      <td>0.03838689</td>
    </tr>
  </tbody>
</table>

<p>While the weighted model performed worse on training data, it improved test set precision by <strong>6%</strong>, suggesting potential benefits in real-world scenarios.</p>

<p>A large overfitting of the model can be observed in the results above with the large differences in MAP@500 between train and test. Moreover, while weighted model performed worse on train data, it managed to improve the precision by 6% on test data.</p>]]></content><author><name>Igor Gukasyan</name><email>igorgukasyan00@gmail.com</email></author><summary type="html"><![CDATA[Motivation Behind the Topic A little over a decade ago, a new genre emerged from the depths of the Russian rap scene. As of now, it has no name (to my knowledge) and can take many forms, though it usually appears as rap. The genre’s distinctive feature is highly conceptual, linguistically experimental, neologism-heavy lyrics. Examples of artists include Ezhemesyachnye, Husky, makulatura, Krovostok and Pasha Technique. I think a name like “solyanka” can stick. Solyanka is a common dish, or rather, a culinary disaster of one, in post-Soviet countries, whose name became a phraseological unit meaning ‘a mix of everything’. In this context, solyanka is used as a metaphor for content-rich. One could argue solyanka the dish is as abstract in its contents as the music of the aforementioned bands.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://igorgukasyan.github.io/assets/images/num_songs_histogram_master_thesis.png" /><media:content medium="image" url="https://igorgukasyan.github.io/assets/images/num_songs_histogram_master_thesis.png" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">Dashboards with Streamlit and Evidence</title><link href="https://igorgukasyan.github.io/2025/03/11/streamlit-and-evidence-happyads.html" rel="alternate" type="text/html" title="Dashboards with Streamlit and Evidence" /><published>2025-03-11T00:00:00+00:00</published><updated>2025-03-11T00:00:00+00:00</updated><id>https://igorgukasyan.github.io/2025/03/11/streamlit-and-evidence-happyads</id><content type="html" xml:base="https://igorgukasyan.github.io/2025/03/11/streamlit-and-evidence-happyads.html"><![CDATA[<p>As a part of my freelance work at a marketing agency HappyAds, I created a series of dashboards to help teams access their data in a fast and convenient manner. I want to share two examples from different frameworks in order to demonstrate my technical versatility and dashboarding experience.</p>

<blockquote>
  <p><strong>The data displayed is random!</strong></p>
</blockquote>

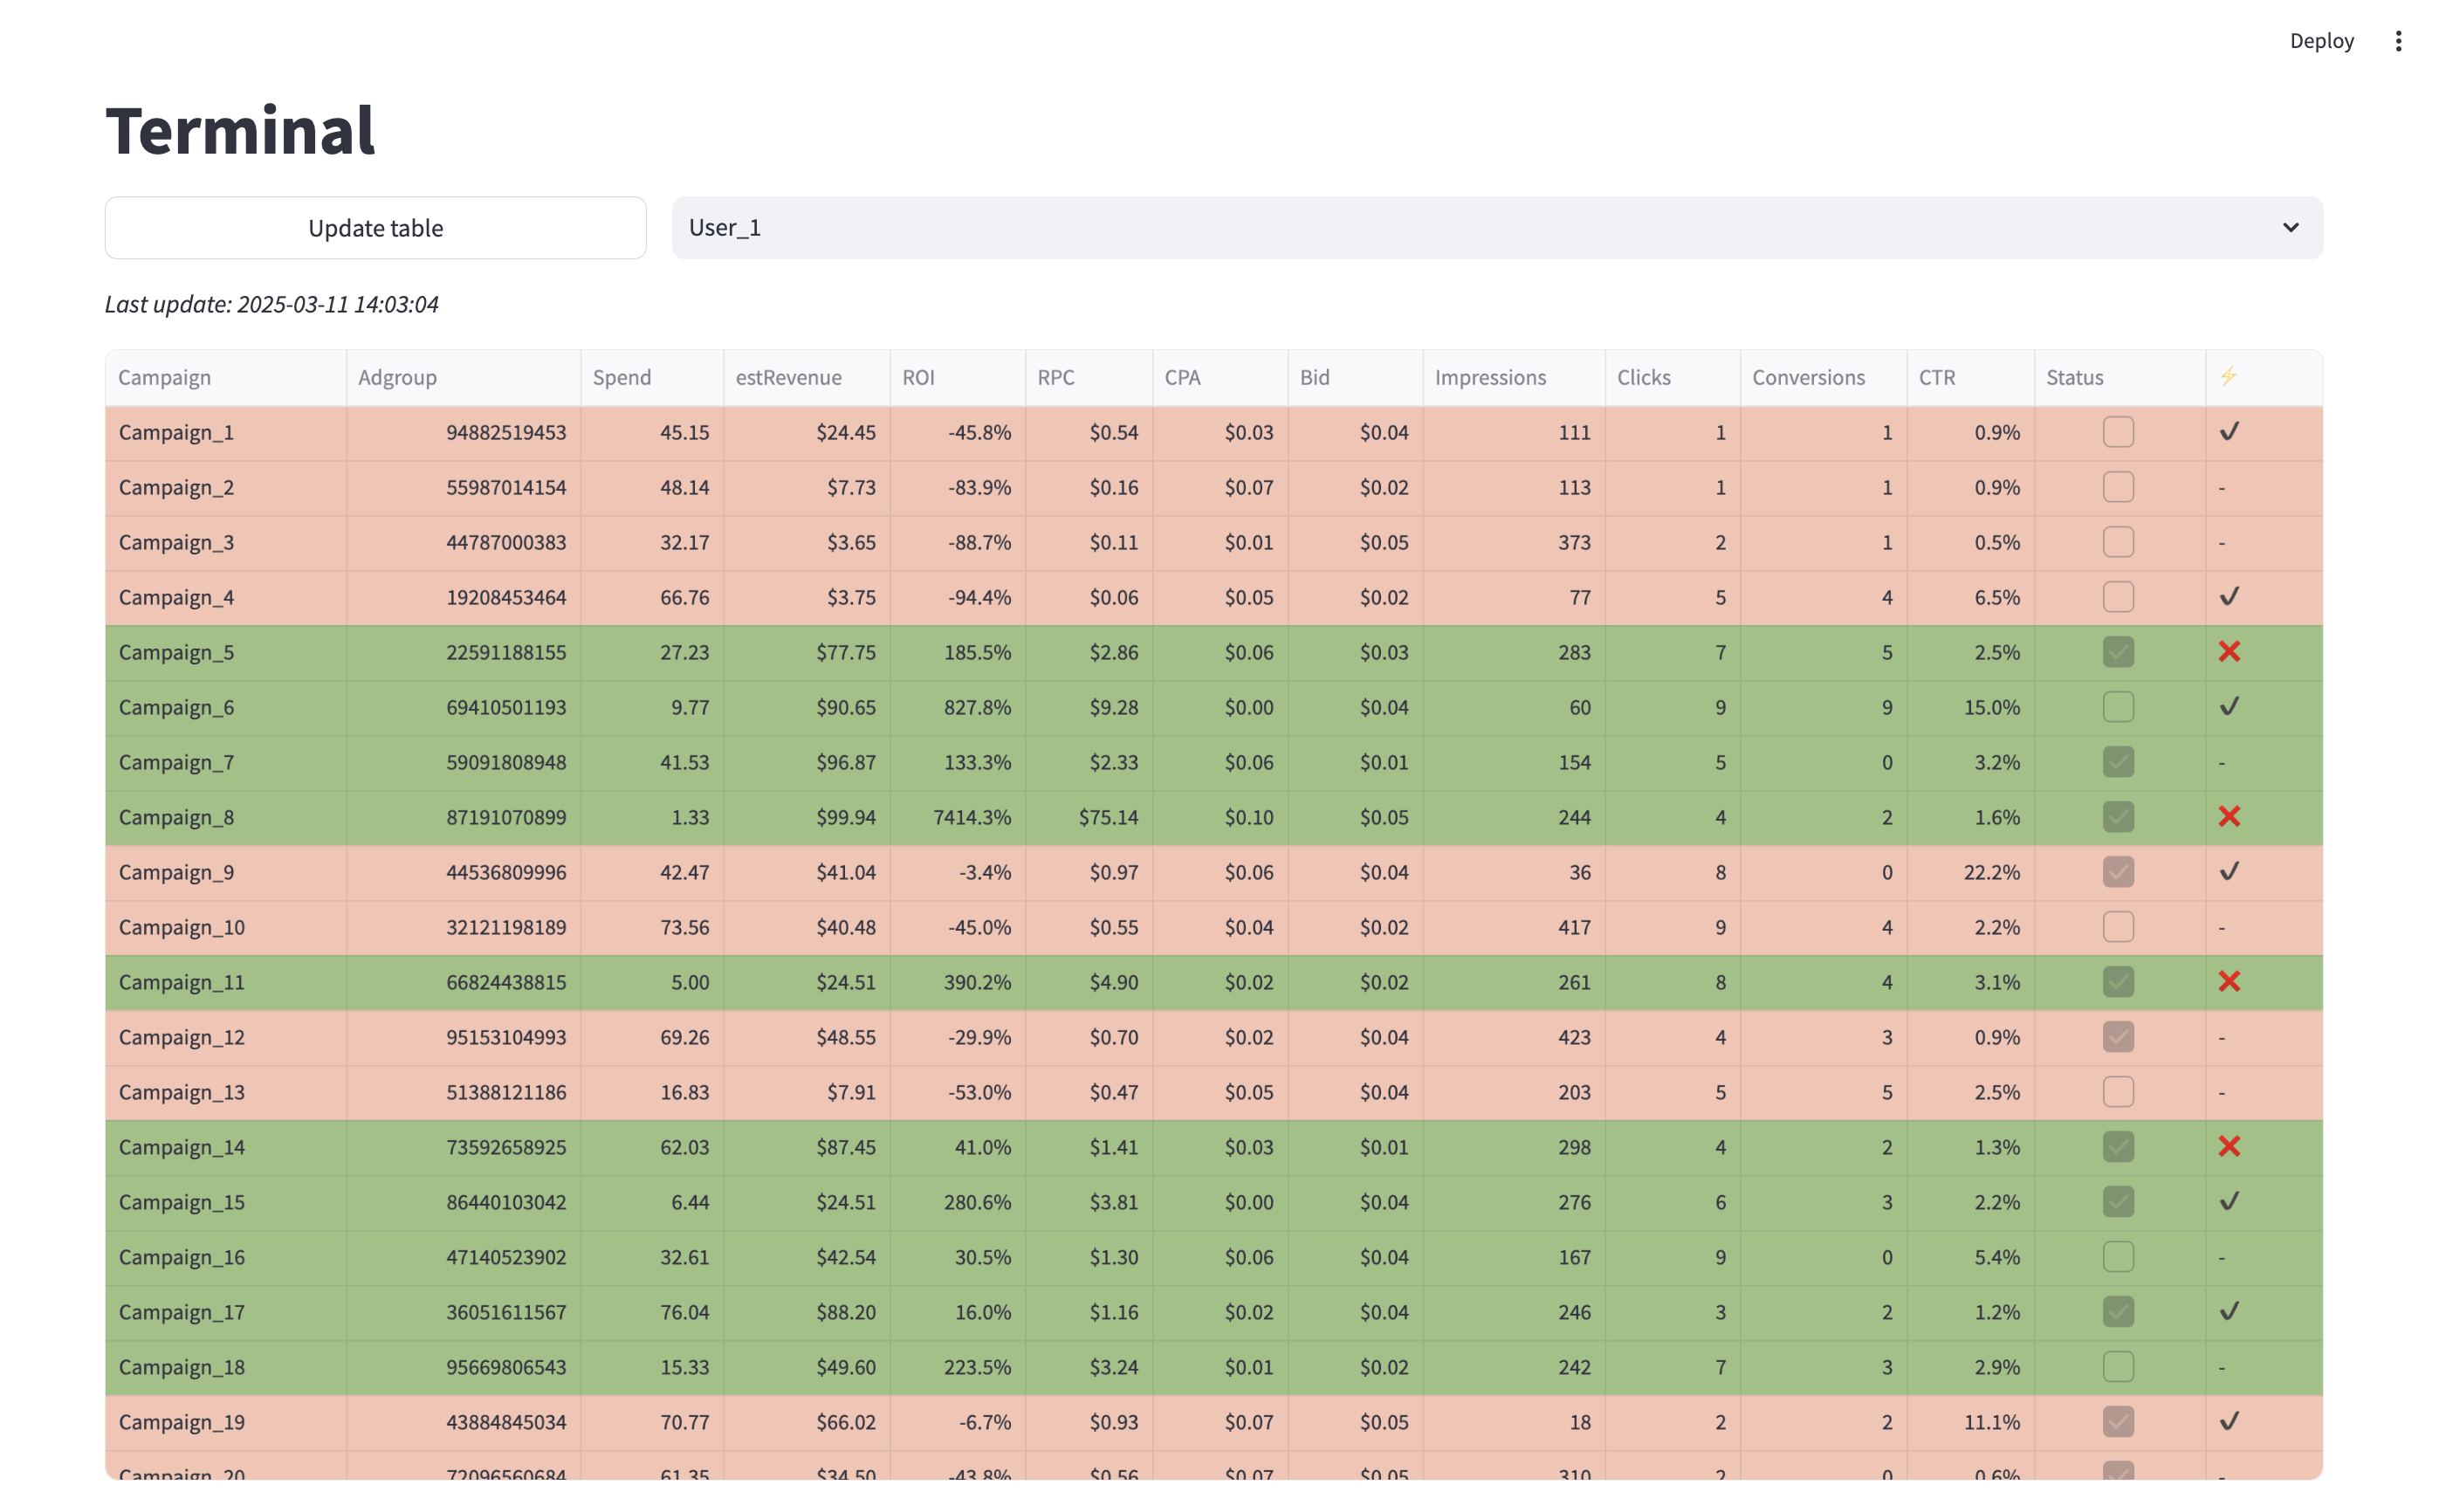
<p>The dashboard below was created using Python and the Streamlit open-source framework. Data is pulled from multiple sources, including the <strong>TikTok API</strong> and <strong>TONIC API</strong>, and is subsequently cleaned and transformed to fit the required format. The last column represents advice of whether to continue with a campaign or not based on the results of a <strong>machine learning model</strong>.</p>

<p>The dashboard is meant to display most relevant and recent data, improving reaction time of the buyer team. Therefore, it includes an ‘Update dashboard’ button that buyers can use to fetch new data outside of a predefined schedule.</p>

<p><img src="/assets/images/streamlit_example.png" alt="" /></p>

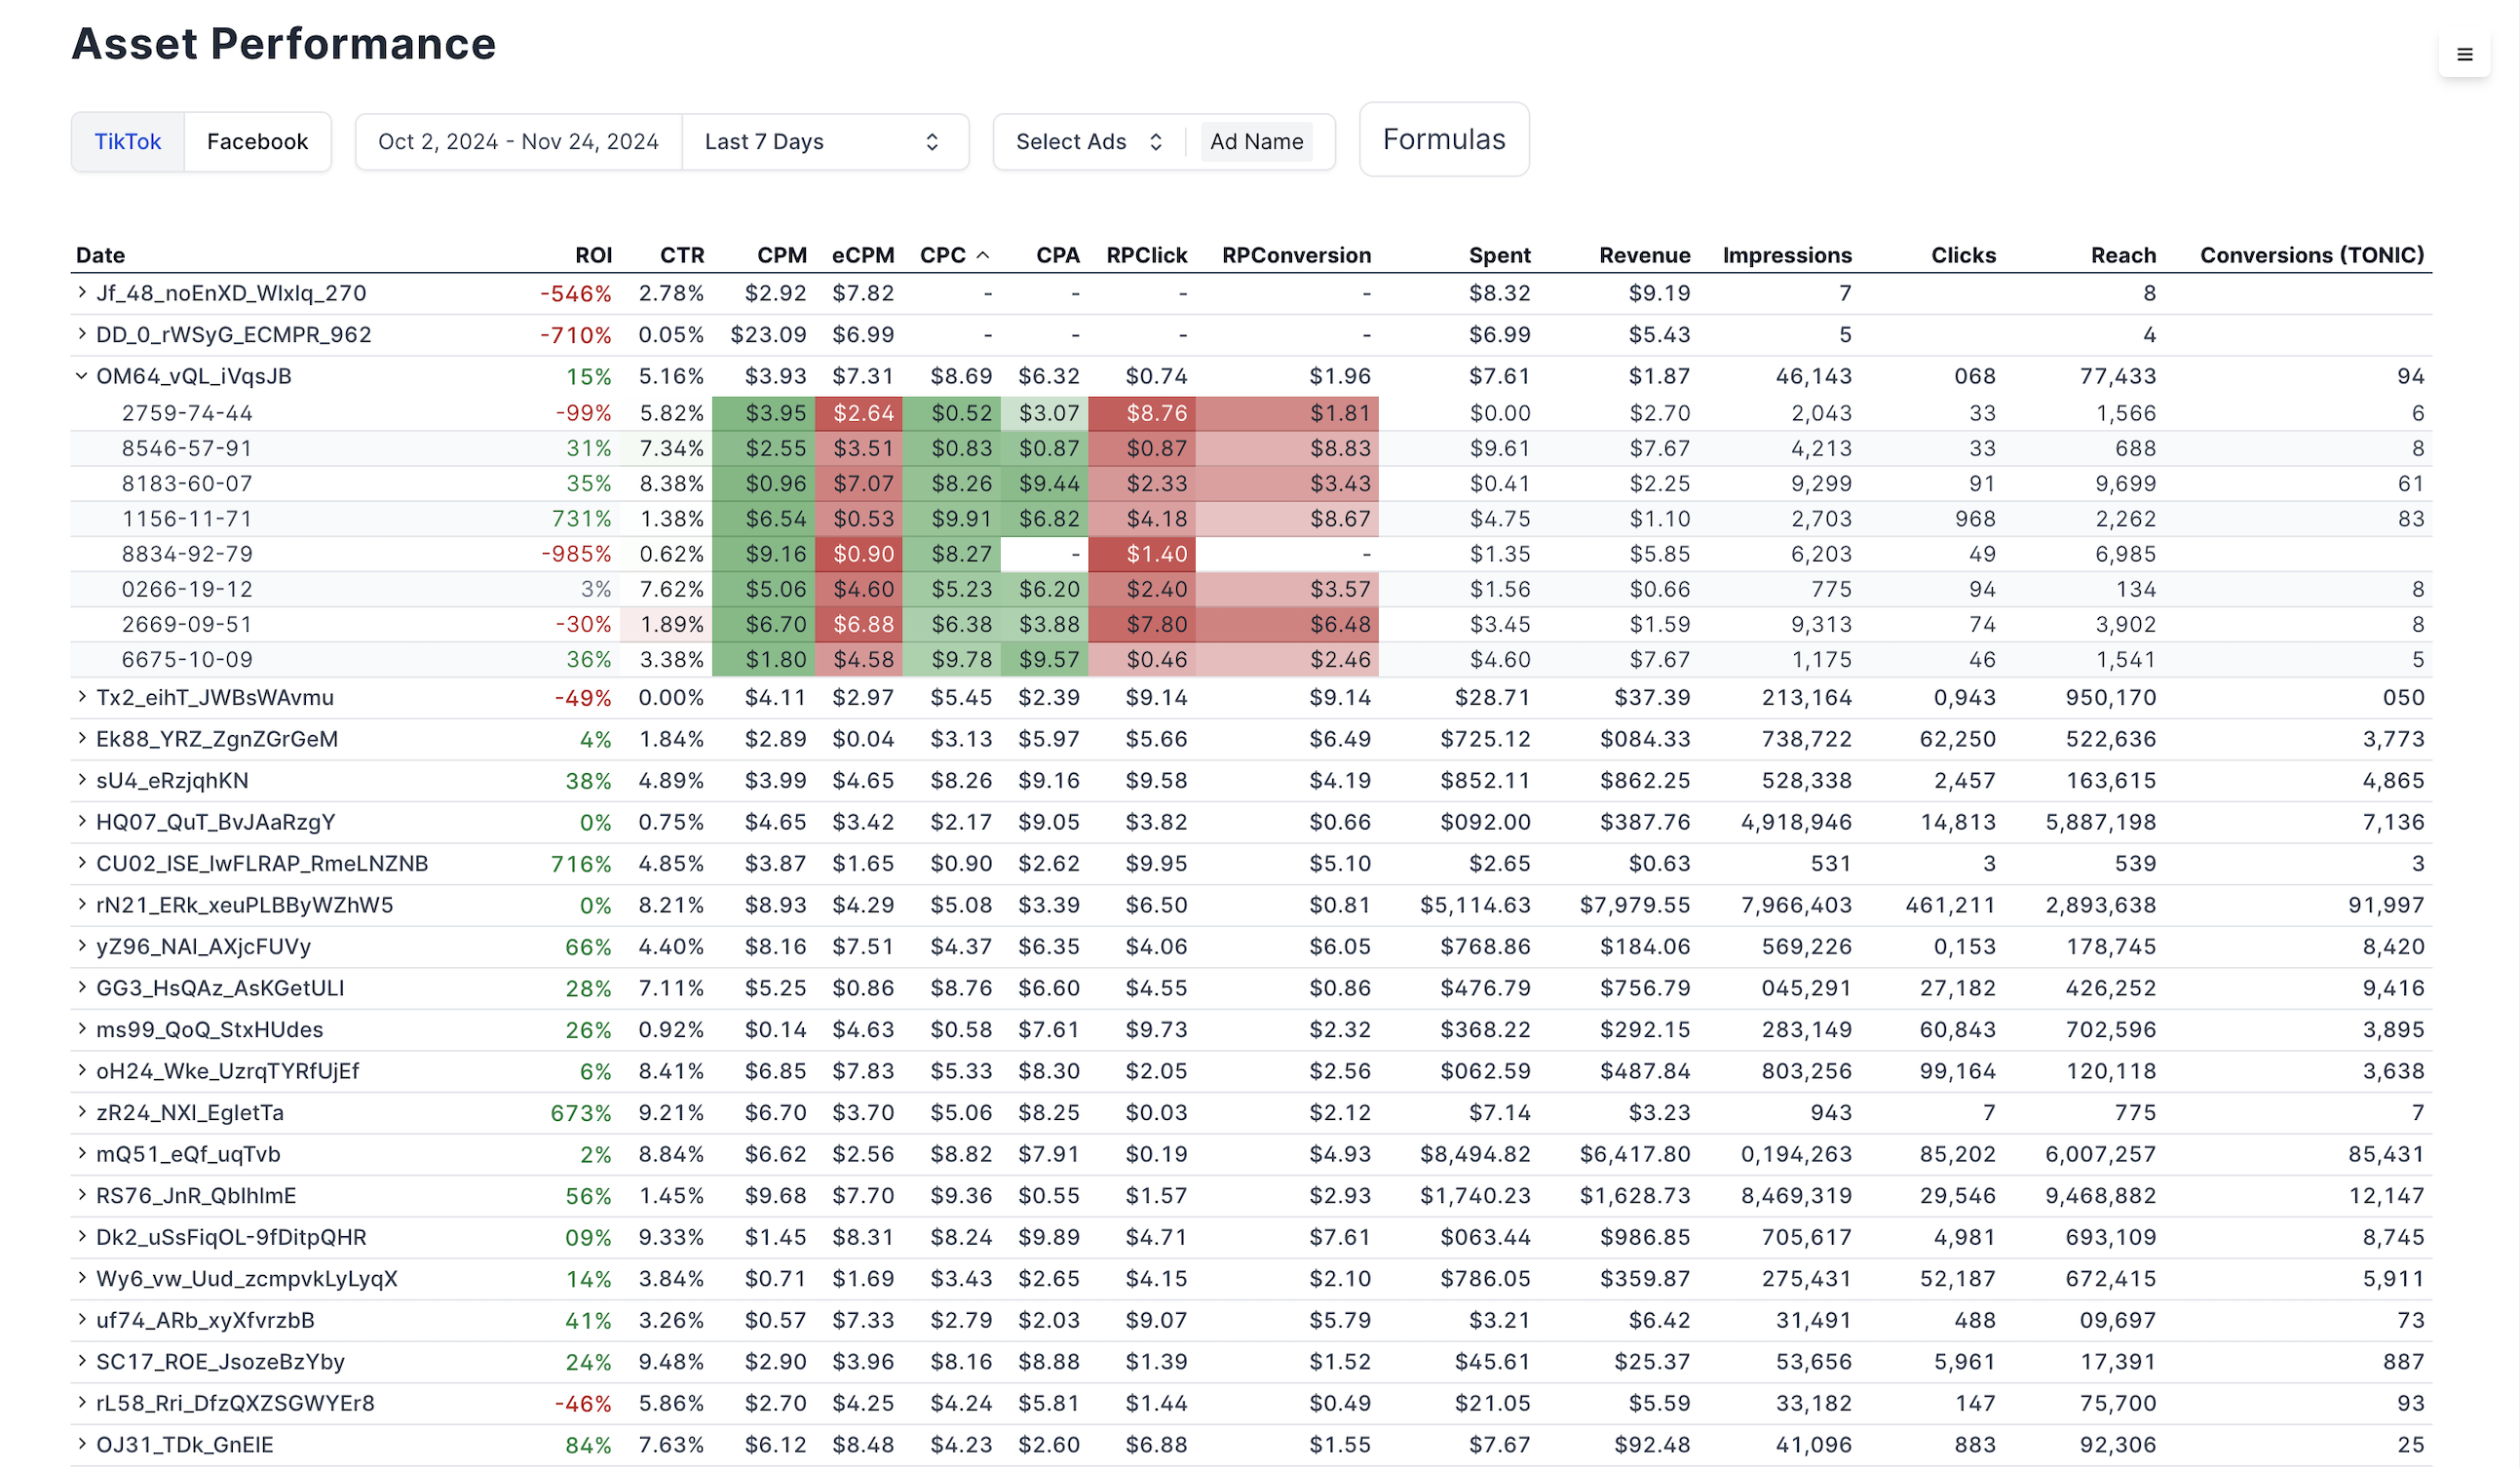
<p>The dashboard below was created using Evidence’s native scripting language and displays the performance of marketing assets. Data is fetched using <strong>ClickFlare API</strong> as well as with <strong>Selenium</strong> from theoptimizer.io. It is afterwards cleaned and queried using <strong>DuckDB</strong> dialect of <strong>SQL</strong>.</p>

<p>The dashboard is designed to reduce the time needed to analyze creative assets while conveniently displaying their performance over various periods.</p>

<p><img src="/assets/images/evidence_example.png" alt="" /></p>]]></content><author><name>Igor Gukasyan</name><email>igorgukasyan00@gmail.com</email></author><summary type="html"><![CDATA[As a part of my freelance work at a marketing agency HappyAds, I created a series of dashboards to help teams access their data in a fast and convenient manner. I want to share two examples from different frameworks in order to demonstrate my technical versatility and dashboarding experience.]]></summary></entry><entry><title type="html">Master Thesis: Enhancing Content-Based Music Recommendation with Lyrical Features</title><link href="https://igorgukasyan.github.io/2025/03/10/master-thesis.html" rel="alternate" type="text/html" title="Master Thesis: Enhancing Content-Based Music Recommendation with Lyrical Features" /><published>2025-03-10T00:00:00+00:00</published><updated>2025-03-10T00:00:00+00:00</updated><id>https://igorgukasyan.github.io/2025/03/10/master-thesis</id><content type="html" xml:base="https://igorgukasyan.github.io/2025/03/10/master-thesis.html"><![CDATA[<p>In September 2025, I successfully defended my thesis at Erasmus School of Economics, Erasmus University, for the ‘Data Science and Marketing Analytics’ program.</p>

<p>In the thesis, I use listening history data from thousands of users across about 40,000 songs to show that certain linguistic features can improve content-based music recommendation systems.
Below, you can find the full version of my work, and the code is posted on github.</p>

<p>In the next post, I will break down my thesis in simpler terms and share some extra thoughts that make it into the paper.</p>

<p class="mobile-only">
    On mobile, <a href="/assets/master_thesis.pdf" target="_blank">click here to view the PDF</a>.
</p>

<iframe class="desktop-only" src="/assets/master_thesis.pdf" width="100%" height="1000px" style="border: none;"></iframe>]]></content><author><name>Igor Gukasyan</name><email>igorgukasyan00@gmail.com</email></author><summary type="html"><![CDATA[In September 2025, I successfully defended my thesis at Erasmus School of Economics, Erasmus University, for the ‘Data Science and Marketing Analytics’ program.]]></summary></entry></feed>